
Hugging Face
CodingHugging Face hosts millions of open models plus datasets and Spaces demo apps, with paid storage, GPUs and inference. Free to browse; PRO is $9 a month.
Model HubDatasets
Together AI is a cloud for open models: serverless APIs for models such as Kimi, DeepSeek and Qwen, dedicated endpoints, fine-tuning and GPU clusters.
Together AI calls itself “the AI Native Cloud.” It lets developers use popular open models without running their own servers: serverless inference bills per token, while provisioned throughput and dedicated endpoints give reserved capacity for production. The same platform offers fine-tuning and post-training, sandboxes, managed storage and GPU clusters. Its catalogue covers chat, image, video, audio and embedding models, and its site lists customers such as Cursor and Decagon.
Editorial suggestion: use it to test a new open model through the API before deciding whether to self-host. Compare the per-token price with the same model on other hosts, and check cached-input pricing if your prompts repeat.
Try new open models
Production APIs
Custom models
Training jobs
Official product image. Click to inspect the details.
Official examples and public-page captures; these are not results from a paid-feature trial.
Call open chat, vision, image, audio and embedding models per token, with cached-input discounts on some models.
Provisioned throughput and dedicated endpoints reserve GPUs for steady production traffic.
Supervised fine-tuning and DPO on models such as Llama, Qwen, gpt-oss and DeepSeek, priced per million tokens.
Rent H100, H200 and B200 GPUs by the hour, preemptible, on demand or reserved.
Create an account
Pick a model
Run a small test
Scale deliberately
Sign up at together.ai and create an API key.
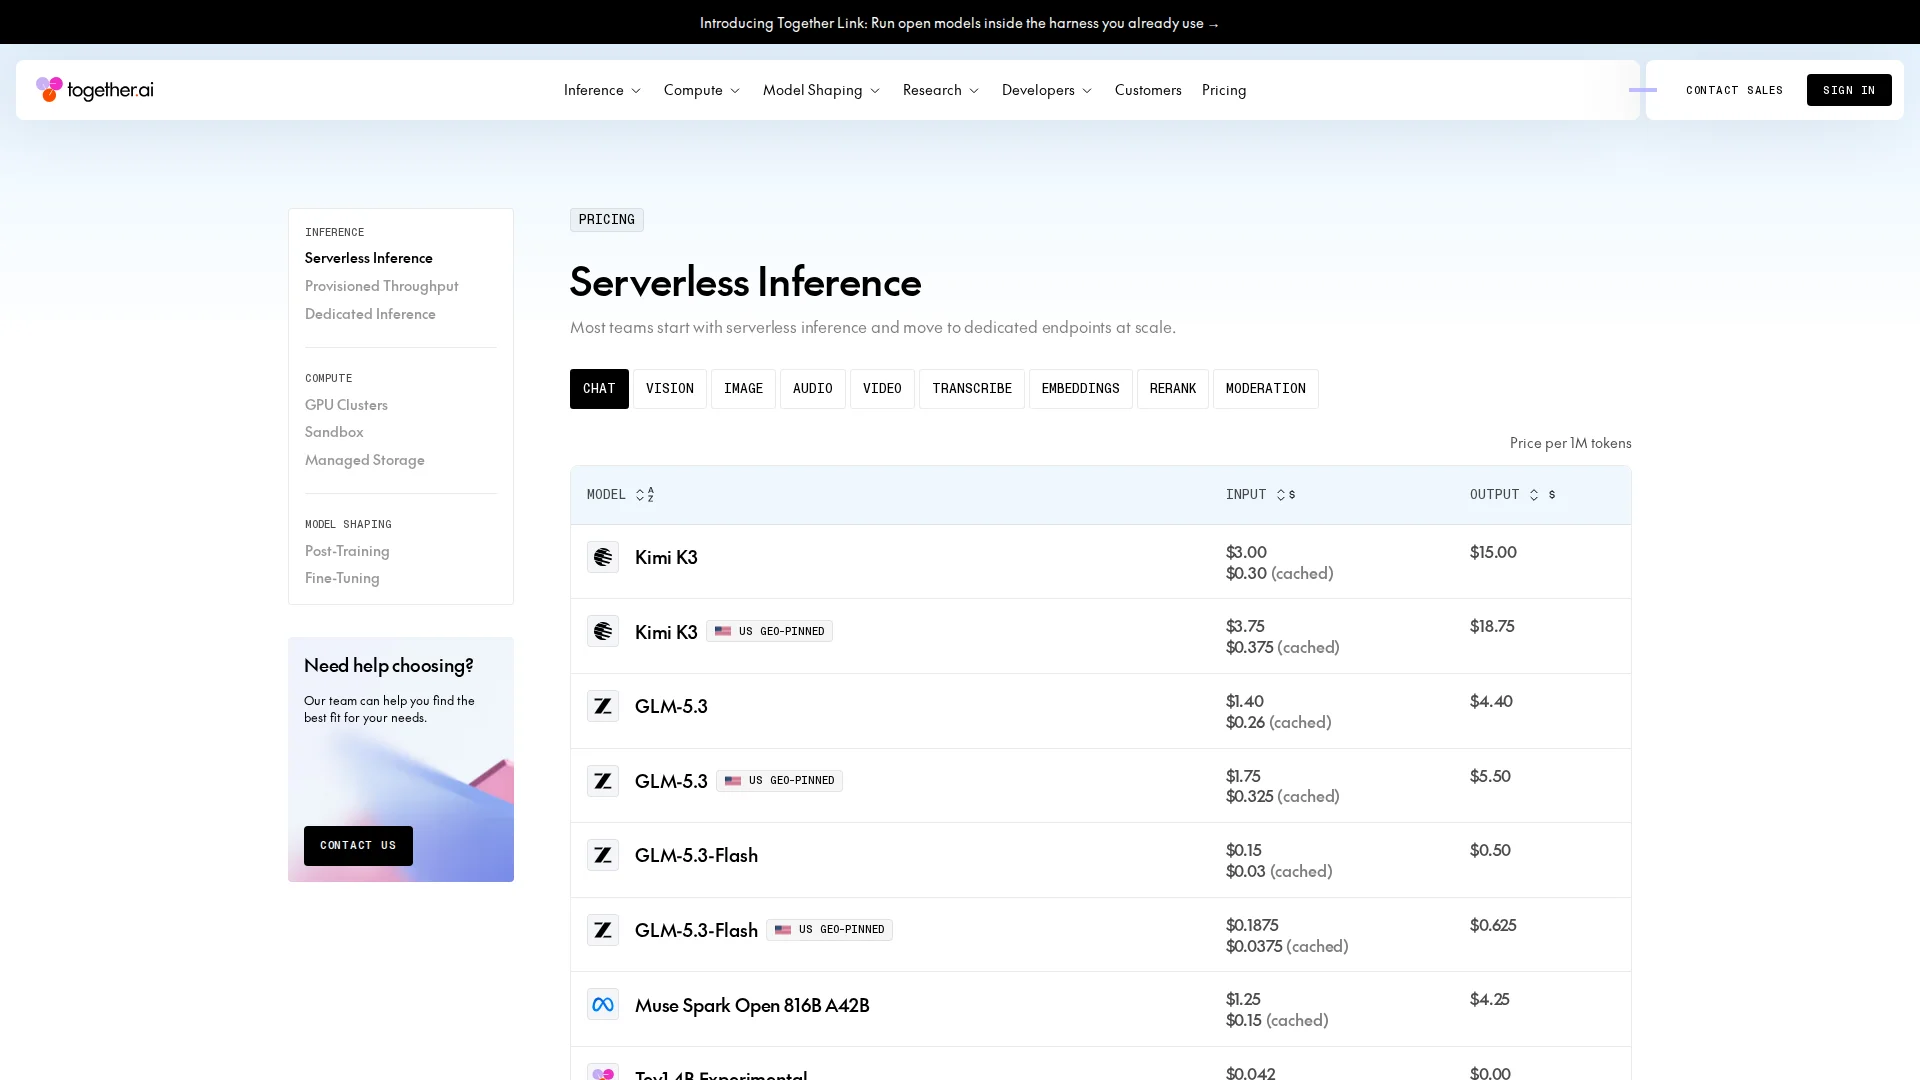
Compare models and prices on the serverless pricing page.
Send a few real prompts and measure quality, latency and cost per request.
Move steady traffic to provisioned or dedicated capacity once usage is predictable.
Serverless prices are per million tokens. Examples: Kimi K3.1 Pro $2.00 input ($0.20 cached) and $10.00 output; DeepSeek V4.1 Flash $0.30 input and $1.20 output; gpt-oss-120B $0.15 and $0.60; Qwen3.5 9B $0.17 and $0.25. A few experimental models are listed as free.
Fine-tuning examples: Llama 3.1 8B at $0.34 per million tokens for SFT ($4 minimum). Dedicated inference starts at $5.49 per H100 hour; GPU clusters list H100 from $1.99 (preemptible) to $3.99 (on demand) per GPU hour.
You can start for free and a few experimental models are free, but most models are billed per token.
Popular open models such as Kimi, DeepSeek, Qwen, GLM, gpt-oss and MiniMax, plus image and video models.
$2.00 per million input tokens ($0.20 cached) and $10.00 per million output tokens on serverless.
Yes, with supervised fine-tuning and DPO priced per million tokens, with a minimum charge per job.
Yes. GPU clusters offer H100, H200 and B200 by the hour, preemptible, on demand or reserved.
Together runs the models on its own infrastructure and also sells fine-tuning and GPUs; OpenRouter routes requests across many providers.
Explore platforms, inputs and outputs, licensing, and access requirements.
These tools overlap with parts of the workflow; compare the specific task, export requirements and current plan rather than treating them as identical products.
Prompts and training data are processed on Together’s infrastructure, so review its data terms before sending customer data, and check whether a model is served in a specific region when that matters. Each open model keeps its own license, which still applies when you call it through an API.
Loading experiences…
Bring a real task and see how it fits the way you work.
User experiences