Murf
Audio & musicCreate voiceovers from scripts and refine delivery with voice, pronunciation and pacing controls. Murf Studio serves content production, while Murf’s API, dubbing and conversational-agent offerings address different workflows.
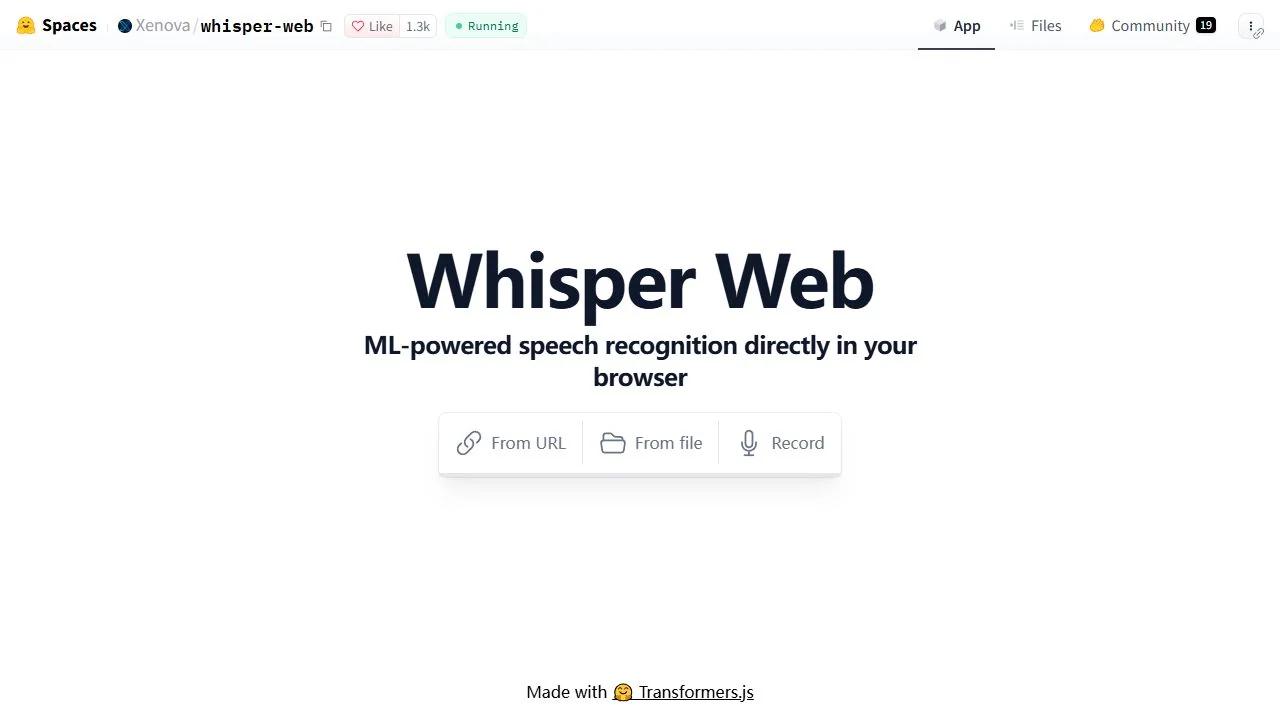
A free browser-based speech-recognition demo built with Transformers.js and Whisper models. It accepts audio from a file, URL or recording and performs inference on the device, with transcript text and JSON export in the documented application.
Whisper Web demonstrates speech recognition running directly in a browser through Transformers.js. It is useful for users who want to try local-device transcription without installing a full desktop transcription suite, and for developers studying how model inference can be integrated into a web interface.
The application downloads the required resources and then processes audio through a browser worker. This is different from paying a hosted transcription service to recognize each recording. It still requires a capable device, memory and initial network access, and the public demo should not be mistaken for an enterprise transcription service with guaranteed availability.
Transcribe a voice memo
Prepare interview notes
Study a recorded explanation
Prototype browser AI
Official product image. Click to inspect the details.

Prepare a short recording
Load the input and model
Inspect the transcript
Export for the next task
Example prompt or task: Transcribe this short authorized recording in its original language, then review names, numbers and unclear phrases against the audio. Export readable text and keep timestamped chunks for later correction.
This is an editorial starting workflow, not a measured performance result.
Whisper Web is MIT-licensed software, and its browser-local recognition route does not require purchasing a per-minute cloud transcription plan. The user's device provides compute, and downloading application and model files uses network bandwidth and storage.
The public Hugging Face demo is a convenient example, not a contractual availability guarantee. Developers can follow the repository's local setup instructions. A separate experimental WebGPU branch exists for acceleration; it should not be confused with the default application's requirements.
Its source is MIT-licensed and the documented browser inference route does not charge per transcription minute.
The application uses a browser worker for model inference, after downloading needed resources.
Initial application and model loading require access to their hosting; a fully offline deployment needs separate preparation.
The interface offers recording, subject to browser permission and device support.
The implementation provides TXT and JSON exports.
Do not assume speaker diarization from the basic transcript workflow.
No. The repository describes experimental WebGPU support in a separate branch.
Explore platforms, inputs and outputs, licensing, and access requirements.
Audio decoding and inference depend on the browser, device memory and selected model. Larger models and long recordings can be more demanding, so evaluate a small sample before relying on the application for an entire archive.
The source code's exports are TXT and JSON, not a complete production subtitle package. Additional processing may be required for speaker labels, subtitle formatting, punctuation conventions or a publication-ready transcript.
Local inference reduces the need to send audio to a remote recognition API, but the hosted page still loads application and model resources from the network. Remote audio URLs also contact their source, so distinguish processing location from all network activity.
For sensitive recordings, inspect the exact deployment and prepare an approved local environment. Obtain recording permission and avoid treating a generated transcript as a verbatim quote until it has been checked against the audio.
Reviewed October 3, 2026. Product facts come from the official sources below. Suggested projects, prompts and review methods are FindGoodAI editorial guidance, not measured performance results.
Loading experiences…
Saved tools are private. Approved comments are public; edits return to moderation. Comment counts include approved comments and replies. Each person has one rating. New ratings are automatically approved; withdrawn, unapproved or invalid ratings do not count. Share real experiences and avoid spam, private information or personal attacks.
For moderation appeals or data requests: support@findgoodai.com
Bring a real task and see how it fits the way you work.
User experiences