
Humata
ProductivitySearch, summarize and compare uploaded documents with source-linked answers. Humata adds team-oriented document access and page-based plans for ongoing knowledge work.
Questions across filesCited passages
A document parsing engine that turns PDFs, scans and supported office files into structured content for AI workflows. Local use avoids a mandatory hosted subscription, with hardware requirements and additional license conditions to review.
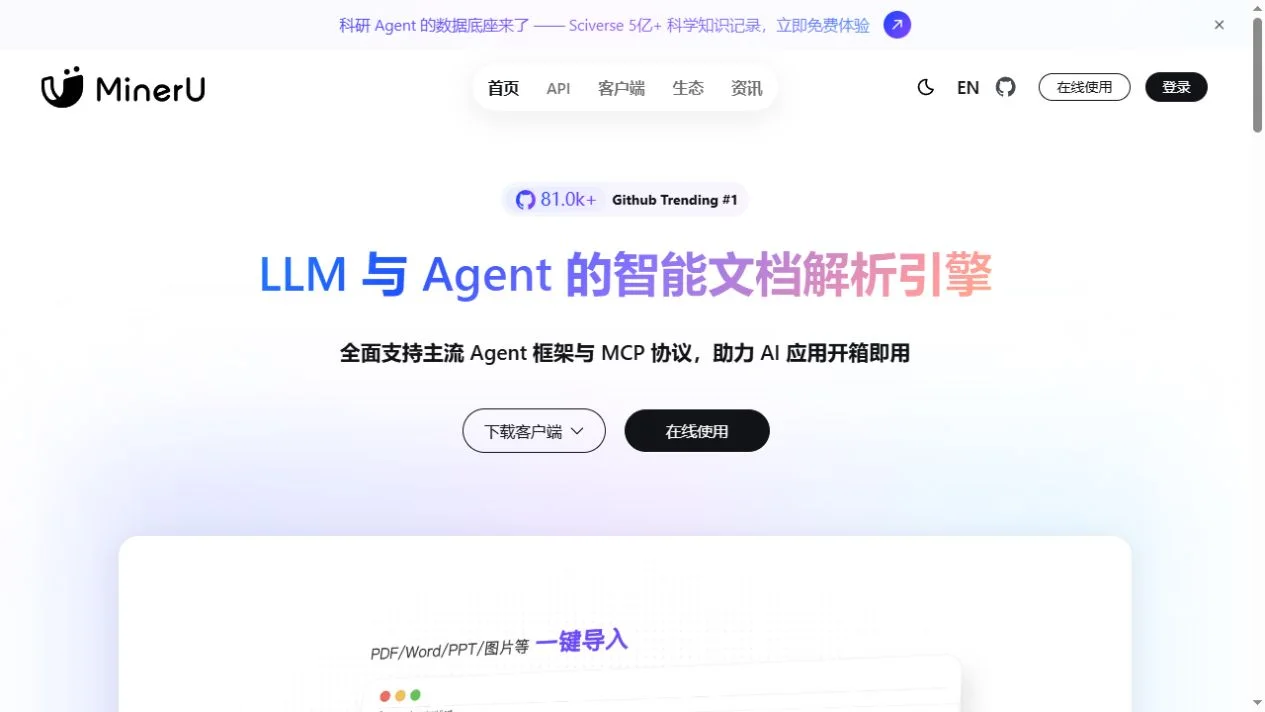
MinerU prepares documents for tasks that need more than a flat copy of their text. It can identify layout and extract material into forms that are easier for an AI application to search, read and cite. This is useful when a PDF contains several columns, tables, formulas or figures whose relationship matters to the meaning of the page.
It is a parsing layer rather than a complete answer engine. A clean extraction helps downstream retrieval and analysis, but it does not establish whether the source itself is correct. The practical objective is to retain enough structure and location information that a later answer can be traced back to the relevant document instead of becoming an unsupported summary.
Prepare a research paper
Build a knowledge-base input
Recover a scanned report
Feed an agent a long document
Official product image. Click to inspect the details.
Select a representative document
Match the local setup
Inspect extraction quality
Connect the reviewed output
Example prompt or task: Parse this public report into structured text, preserve page references, and flag tables or formulas that need visual review before the content enters a knowledge base.
This is a proposed processing workflow. The page does not claim a measured extraction accuracy or speed on your documents.
The current license is based on Apache 2.0 with additional commercial-threshold and attribution conditions.
The local software provides a free route without a mandatory hosted subscription. You supply the computer, storage and any necessary acceleration; optional remote parsing and hosted services should be evaluated under their own terms rather than assumed to be unlimited and free.
The current license is based on Apache 2.0 with additional conditions. It requires attribution for online services provided to third parties and a separate commercial license if the specified consolidated thresholds are exceeded: more than 100 million monthly active users or more than US$20 million total monthly revenue. Review the actual license for your deployment.
Its core role is document parsing; another application can use the extracted content for answers.
Yes, the project documents local pipelines and hardware choices.
Not for the local route, although hardware and optional external services can cost money.
Supported OCR pipelines can, but recognition quality still needs review.
No. The output contract says interfaces expose different subsets.
No. The current license includes additional attribution and commercial-threshold conditions.
No. Compare critical values and table relationships with the source page.
Explore platforms, inputs and outputs, licensing, and access requirements.
The current project supports PDFs, images and several office or web document formats, with different parsing tiers and export availability. Plain text does not need the same OCR path. Check the current format contract instead of applying one configuration to every file type.
Hardware requirements depend on the tier and inference backend. A CPU-compatible route exists, but that does not mean a large archive will process quickly on every laptop. Estimate capacity with a small representative sample and include model storage in the deployment plan.
Keep the local route local by checking the selected backend and whether remote parsing has been enabled. A locally installed application can still transmit documents when configured to use a hosted service.
Restrict access to source documents, extracted text and caches. Parsed output can make sensitive information easier to search, so protect the derived files as carefully as the originals and retain only what the downstream task needs.
Reviewed October 3, 2026. Product facts come from the official sources below. Suggested projects, prompts and review methods are FindGoodAI editorial guidance, not measured performance results.
Loading experiences…
Saved tools are private. Approved comments are public; edits return to moderation. Comment counts include approved comments and replies. Each person has one rating. New ratings are automatically approved; withdrawn, unapproved or invalid ratings do not count. Share real experiences and avoid spam, private information or personal attacks.
For moderation appeals or data requests: support@findgoodai.com
Bring a real task and see how it fits the way you work.
User experiences