JetBrains Junie
CodingJunie combines a coding agent with planning, model choice and JetBrains development workflows. Use the CLI, supported IDE integration or repository automation to work on scoped code changes.
A local runtime for downloading and running language models through a desktop, command-line or API workflow. Local use is free software on your own hardware; cloud-hosted models and the licenses of downloaded models are separate.
Ollama provides a practical way to run supported language models without building an inference server from scratch. It handles the local runtime and model workflow, giving a developer or curious user a relatively direct route from downloading a model to asking a question or calling an API. It can also serve as the model layer behind another application.
The important distinction is between the runtime, the model and the interface around it. Ollama is not a guarantee that any computer can run any model quickly, and it does not make every model equally capable. The best first choice is a model that fits available memory and performs adequately on a specific task, with room left for the rest of the computer’s workload.
Prototype a private text helper
Compare small models
Power a local knowledge app
Learn API integration
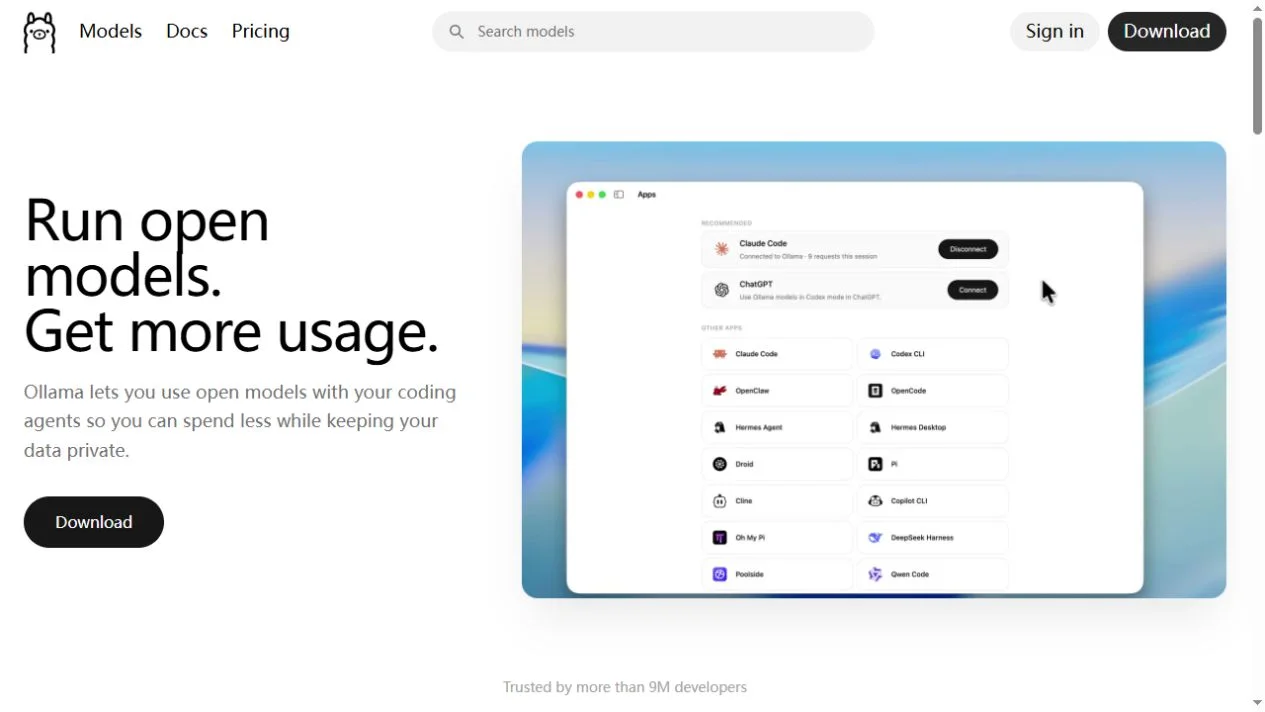
Official product image. Click to inspect the details.

Choose a supported setup
Select an appropriate model
Try one bounded task
Connect and protect
Example prompt or task: Summarize the supplied public notes into three sections: confirmed facts, open questions and next steps. Preserve all numbers, and do not invent missing names or dates.
This is a suggested local-model task. Quality depends on the selected model and configuration, not merely on using Ollama.
Free local execution does not imply every cloud model is unlimited or every downloaded model has the same commercial license.
The runtime is released under MIT, and the current product page explicitly states that local models are free to run. You provide hardware, electricity and storage. There is no universal free performance level: a model that exceeds available memory may run poorly or fail to load.
Cloud plans and additional hosted usage are separate. Each model can also carry its own license, so a free runtime is not a blanket commercial-use grant for every weight file. Inspect the model’s terms and the actual cloud plan before using either in a paid product or a recurring production workflow.
The runtime is free software; local inference uses your own resources.
Not for an appropriately configured local-model workflow.
No. Memory, acceleration, model size and context all matter.
No. Cloud inference is processed by the hosted service rather than your computer.
Yes. The FAQ documents a local-only configuration option.
No. The runtime license and individual model licenses are separate.
No. Evaluate the selected model and verify important outputs.
Explore platforms, inputs and outputs, licensing, and access requirements.
Official routes cover Windows, macOS and Linux. GPU support and acceleration vary by platform and device, and a larger context consumes more memory. The FAQ’s running-model inspection can help determine whether work is on CPU, GPU or a combination.
The local service binds to localhost by default. Exposing it to a network changes who may reach it and requires an appropriate access-control design. Do not casually turn a private local experiment into an unauthenticated public model endpoint.
Ollama’s FAQ states that local prompts and data are not seen by the company when models run locally. Confirm that you selected a local model and that the surrounding application does not separately upload documents, logs or prompts.
Keep the API restricted and inspect connected tools before granting access to files or command execution. Local inference can improve control over data, but it does not automatically secure the rest of an agent workflow or remove the need for backups and access boundaries.
Reviewed October 3, 2026. Product facts come from the official sources below. Suggested projects, prompts and review methods are FindGoodAI editorial guidance, not measured performance results.
Loading experiences…
Saved tools are private. Approved comments are public; edits return to moderation. Comment counts include approved comments and replies. Each person has one rating. New ratings are automatically approved; withdrawn, unapproved or invalid ratings do not count. Share real experiences and avoid spam, private information or personal attacks.
For moderation appeals or data requests: support@findgoodai.com
Bring a real task and see how it fits the way you work.
User experiences